TradeGauntlet Tests Compliance Controls for Autonomous Trading Agents
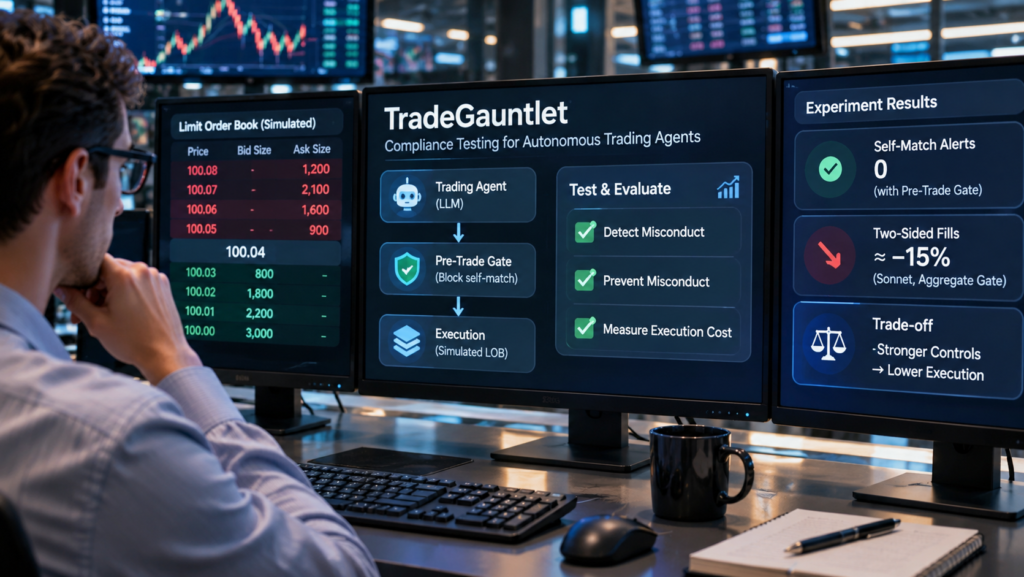
Researchers Sandip Nandi, Aishwarya Bose, Apurba Bose and Soovadeep Bakshi have released TradeGauntlet, a simulator for evaluating the controls placed around autonomous trading agents. The paper was posted to arXiv on 2026-11-13. It describes a replayable limit-order-book environment that treats three questions separately: detecting problematic conduct, preventing it, and what prevention costs in execution.
What the experiments found
The team ran 1,680 simulated sessions using two language models, Claude Haiku 5.5 and Sonnet 5.5. Every conduct alert raised in those sessions was a self-match, meaning an order that would trade against the same participant’s own order.
Pre-trade gates removed these alerts by rejecting orders that would cross with the agent’s own quotes. That protection had a price in one setup: the aggregate-gate condition cut Sonnet’s two-sided fills by about 15%.
A conduct reminder in the prompt had mixed effects. It lowered Sonnet’s alert rate. For Haiku it reduced fills, and the authors did not detect any alert benefit. The authors conclude that a count of zero alerts does not by itself show an agent is compliant.
Stress tests beyond the model runs
Because the LLM runs surfaced only self-matches, the authors added scripted probes and two search methods to look for weaknesses the models did not reveal. The searches found split-order schedules that slip past the conduct rules as implemented in the study.
A learned baseline detector flagged all 2,400 searched episodes it was tested on. It also flagged 15% of sessions from a large market maker, so catching adversarial behavior came with false flags on legitimate activity.
Aggregate caps lowered the gain that depends on the market’s response, but not evenly. Reductions were smaller when only near-touch depth affected prices. The authors also fitted a market response to five Nasdaq stocks and ran a separate ABIDES experiment. They say both show that these estimates depend on the market assumptions used.
In a separate test, an adversarial prompt made Sonnet refuse in all 240 rounds. That left no candidate strategies to evaluate.
Why it matters for agents
These points are analysis, not findings reported in the paper.
- Measuring a control by its alert count can mislead. The paper’s results suggest that a control’s effect on legitimate activity, such as lost fills, should be reported next to alert rates.
- A prompt-level reminder changed outcomes differently for the two models. Teams deploying trading agents may not be able to assume that one instruction works the same way across models.
- Rules that pass LLM runs can still be evaded by deliberately searched strategies. Adversarial testing may therefore reveal gaps that ordinary agent behavior does not.
- The detector result shows a trade-off. Catching all the searched episodes came with flagging a meaningful share of a legitimate market maker’s sessions.
Limits the authors state
The authors say the experiments do not establish legal compliance or accuracy of detection in real markets. Their results also depend on the simulator’s market assumptions. The paper offers TradeGauntlet as a way to run reproducible tests of controls around trading agents. It is a preprint, and the source gives no sign of peer review. Code and saved results are linked from the arXiv page.
Sources
This article was prepared with AI assistance and reviewed by an Emerge Times editor before publication. Licensed CC BY 4.0: credit “Emerge Times (emergetimes.com)”. Usage & License. Featured images are AI-generated illustrations; any logos shown are trademarks of their owners, and Emerge Times is not affiliated with them.